ReImaGin · COLM 2026

Reasoning with Image Generation

Current LLMs reason only in words. ReImaGin lets them reason with images too.
Text and generated images become part of the same reasoning process.

User

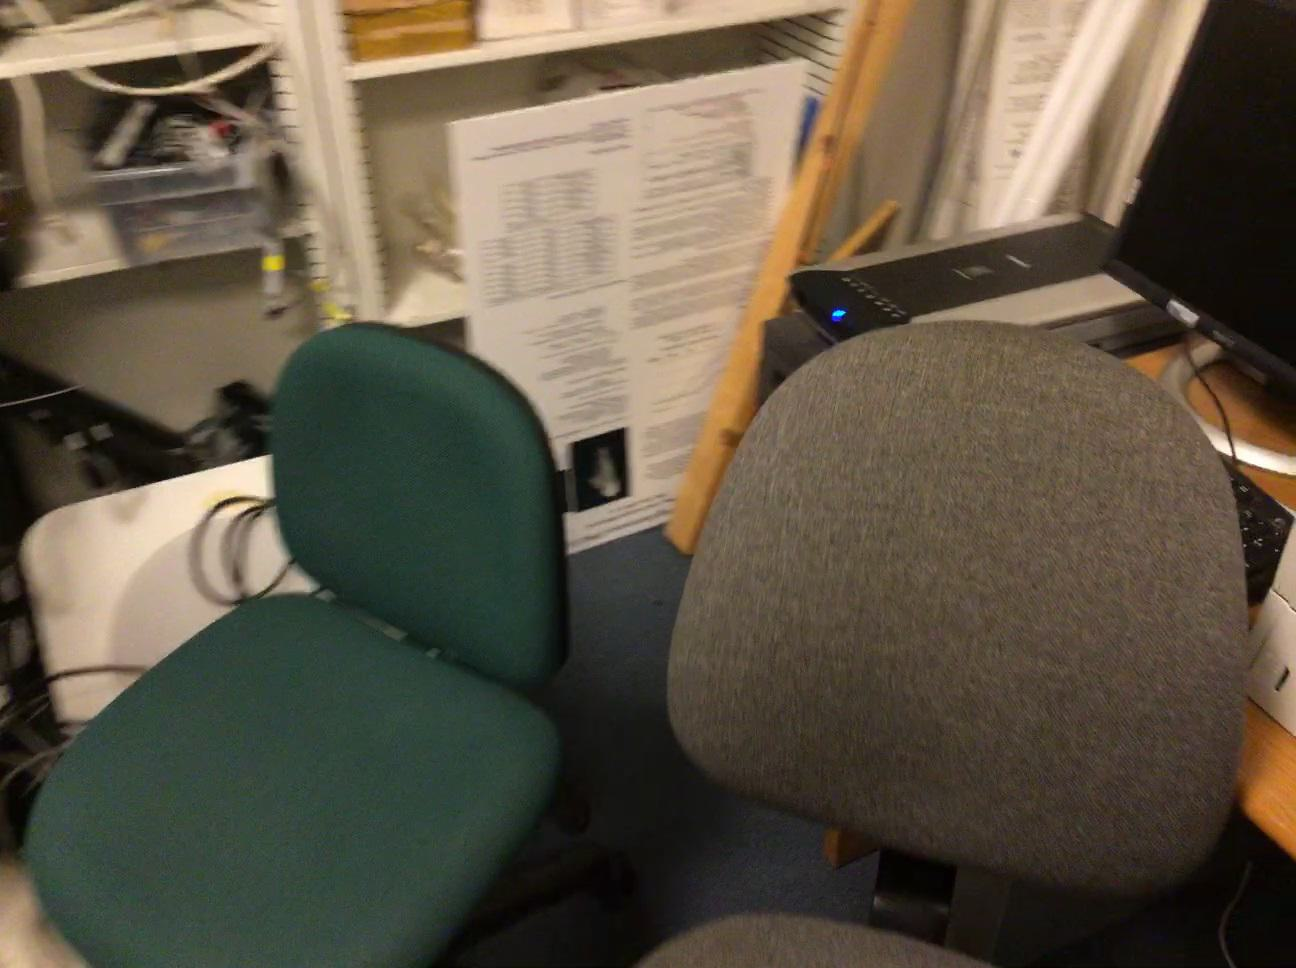
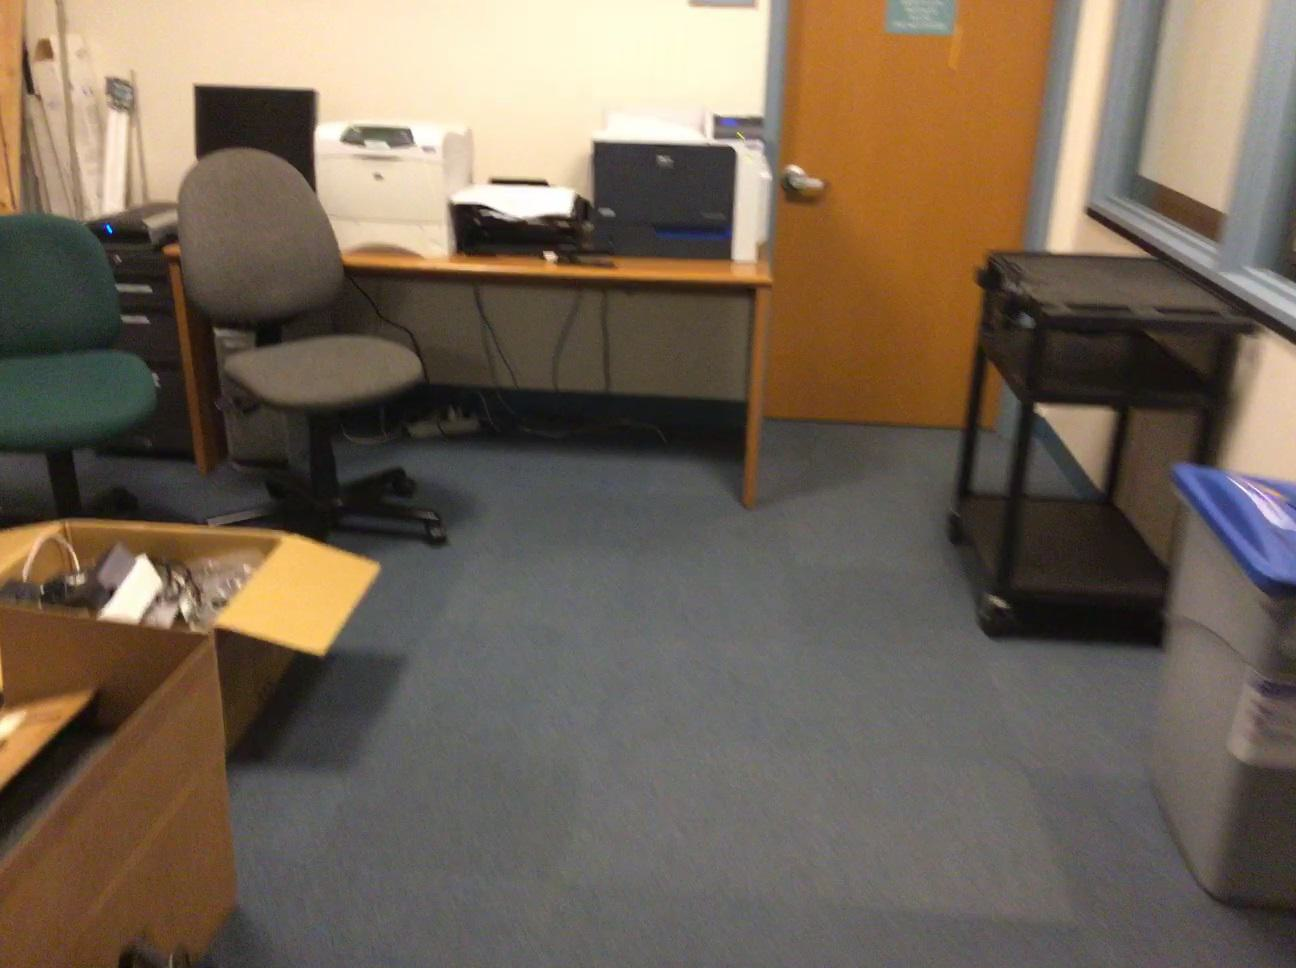
After you enter the door, in which direction is the paper covered with writing?

A: Directly to your left · B: Front right · C: Directly to your right · D: Front left

First office view containing the paper Second office view containing the door
ReImaGin

I need to understand the spatial layout of the room to determine the direction of the paper covered with writing relative to the door. I will use the generate_image tool…

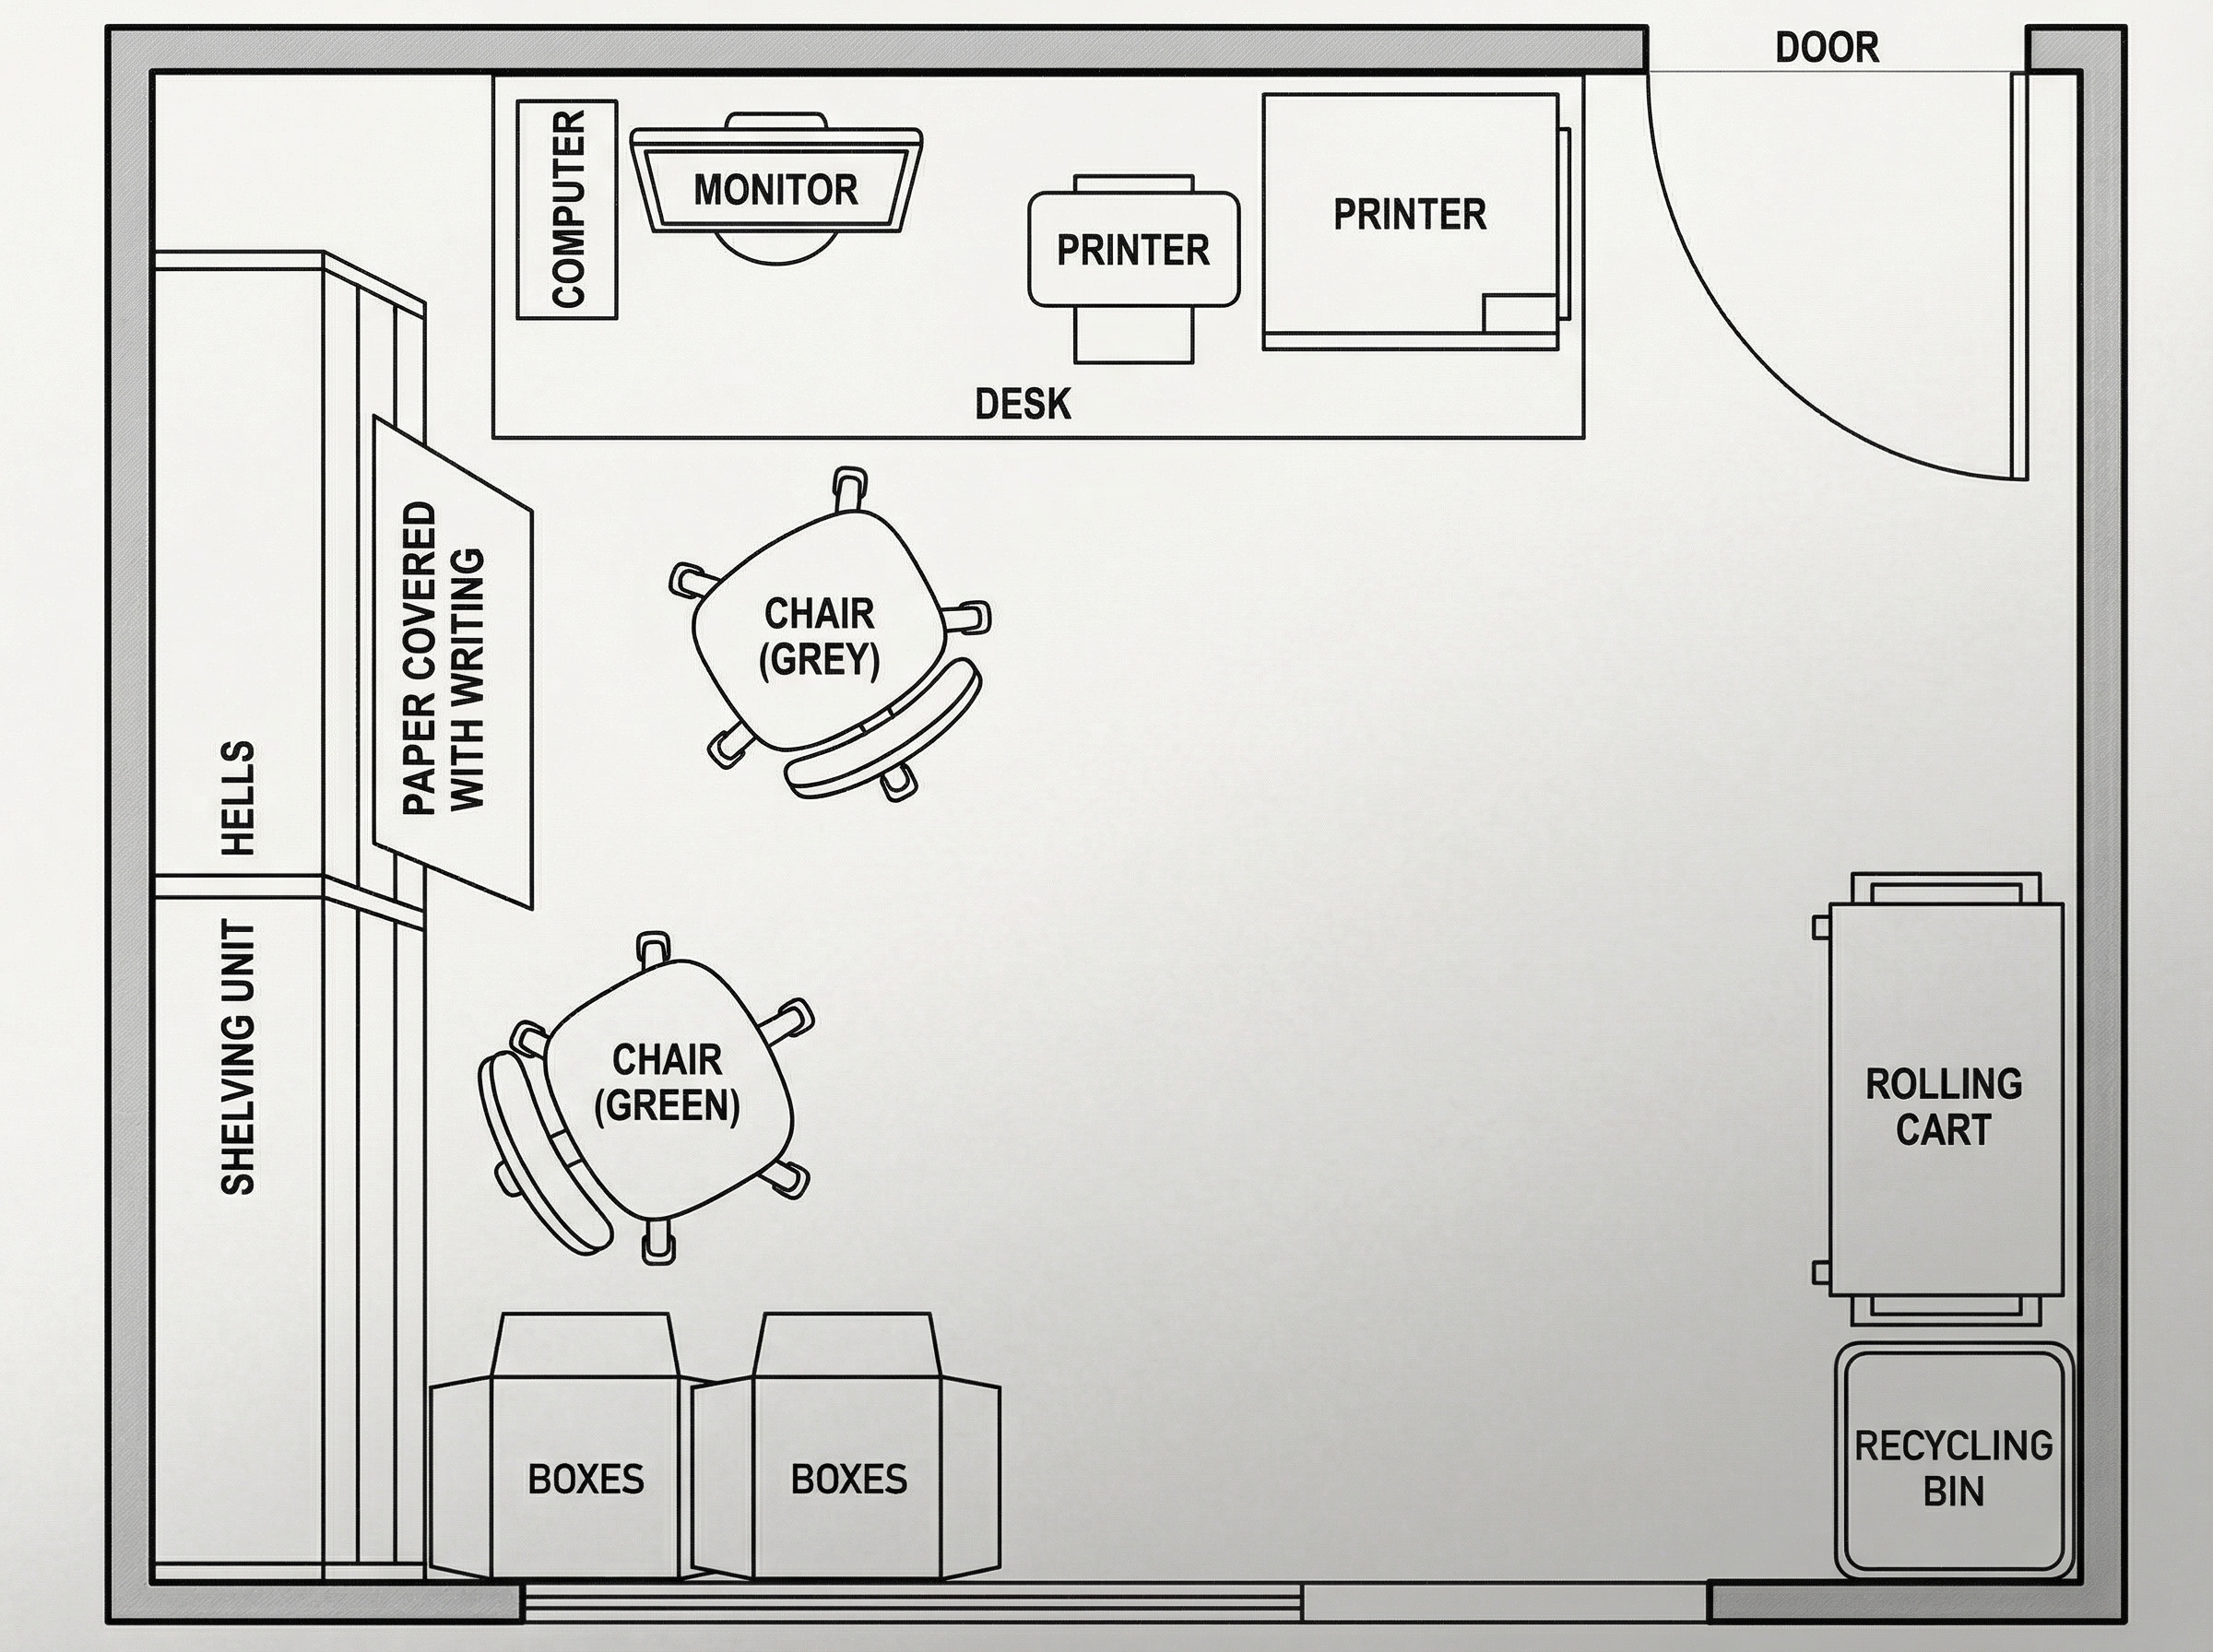
generate_image(“Based on the scene shown in this image, create a *top-down blueprint* of the scene. The accuracy of the layout is extremely important. Label the door, the paper covered with writing, and the chairs. It is important that the orientation and layout of these objects is accurate. Triple check your layout before returning the output.”)
Generated top-down blueprint of the office

Answer: C — Directly to your right ✓

Video overview

ReImaGin, explained.

When words fall short, generate a better view.

The model calls an instruction-following image generator to create the visual intermediate that the problem requires.

User

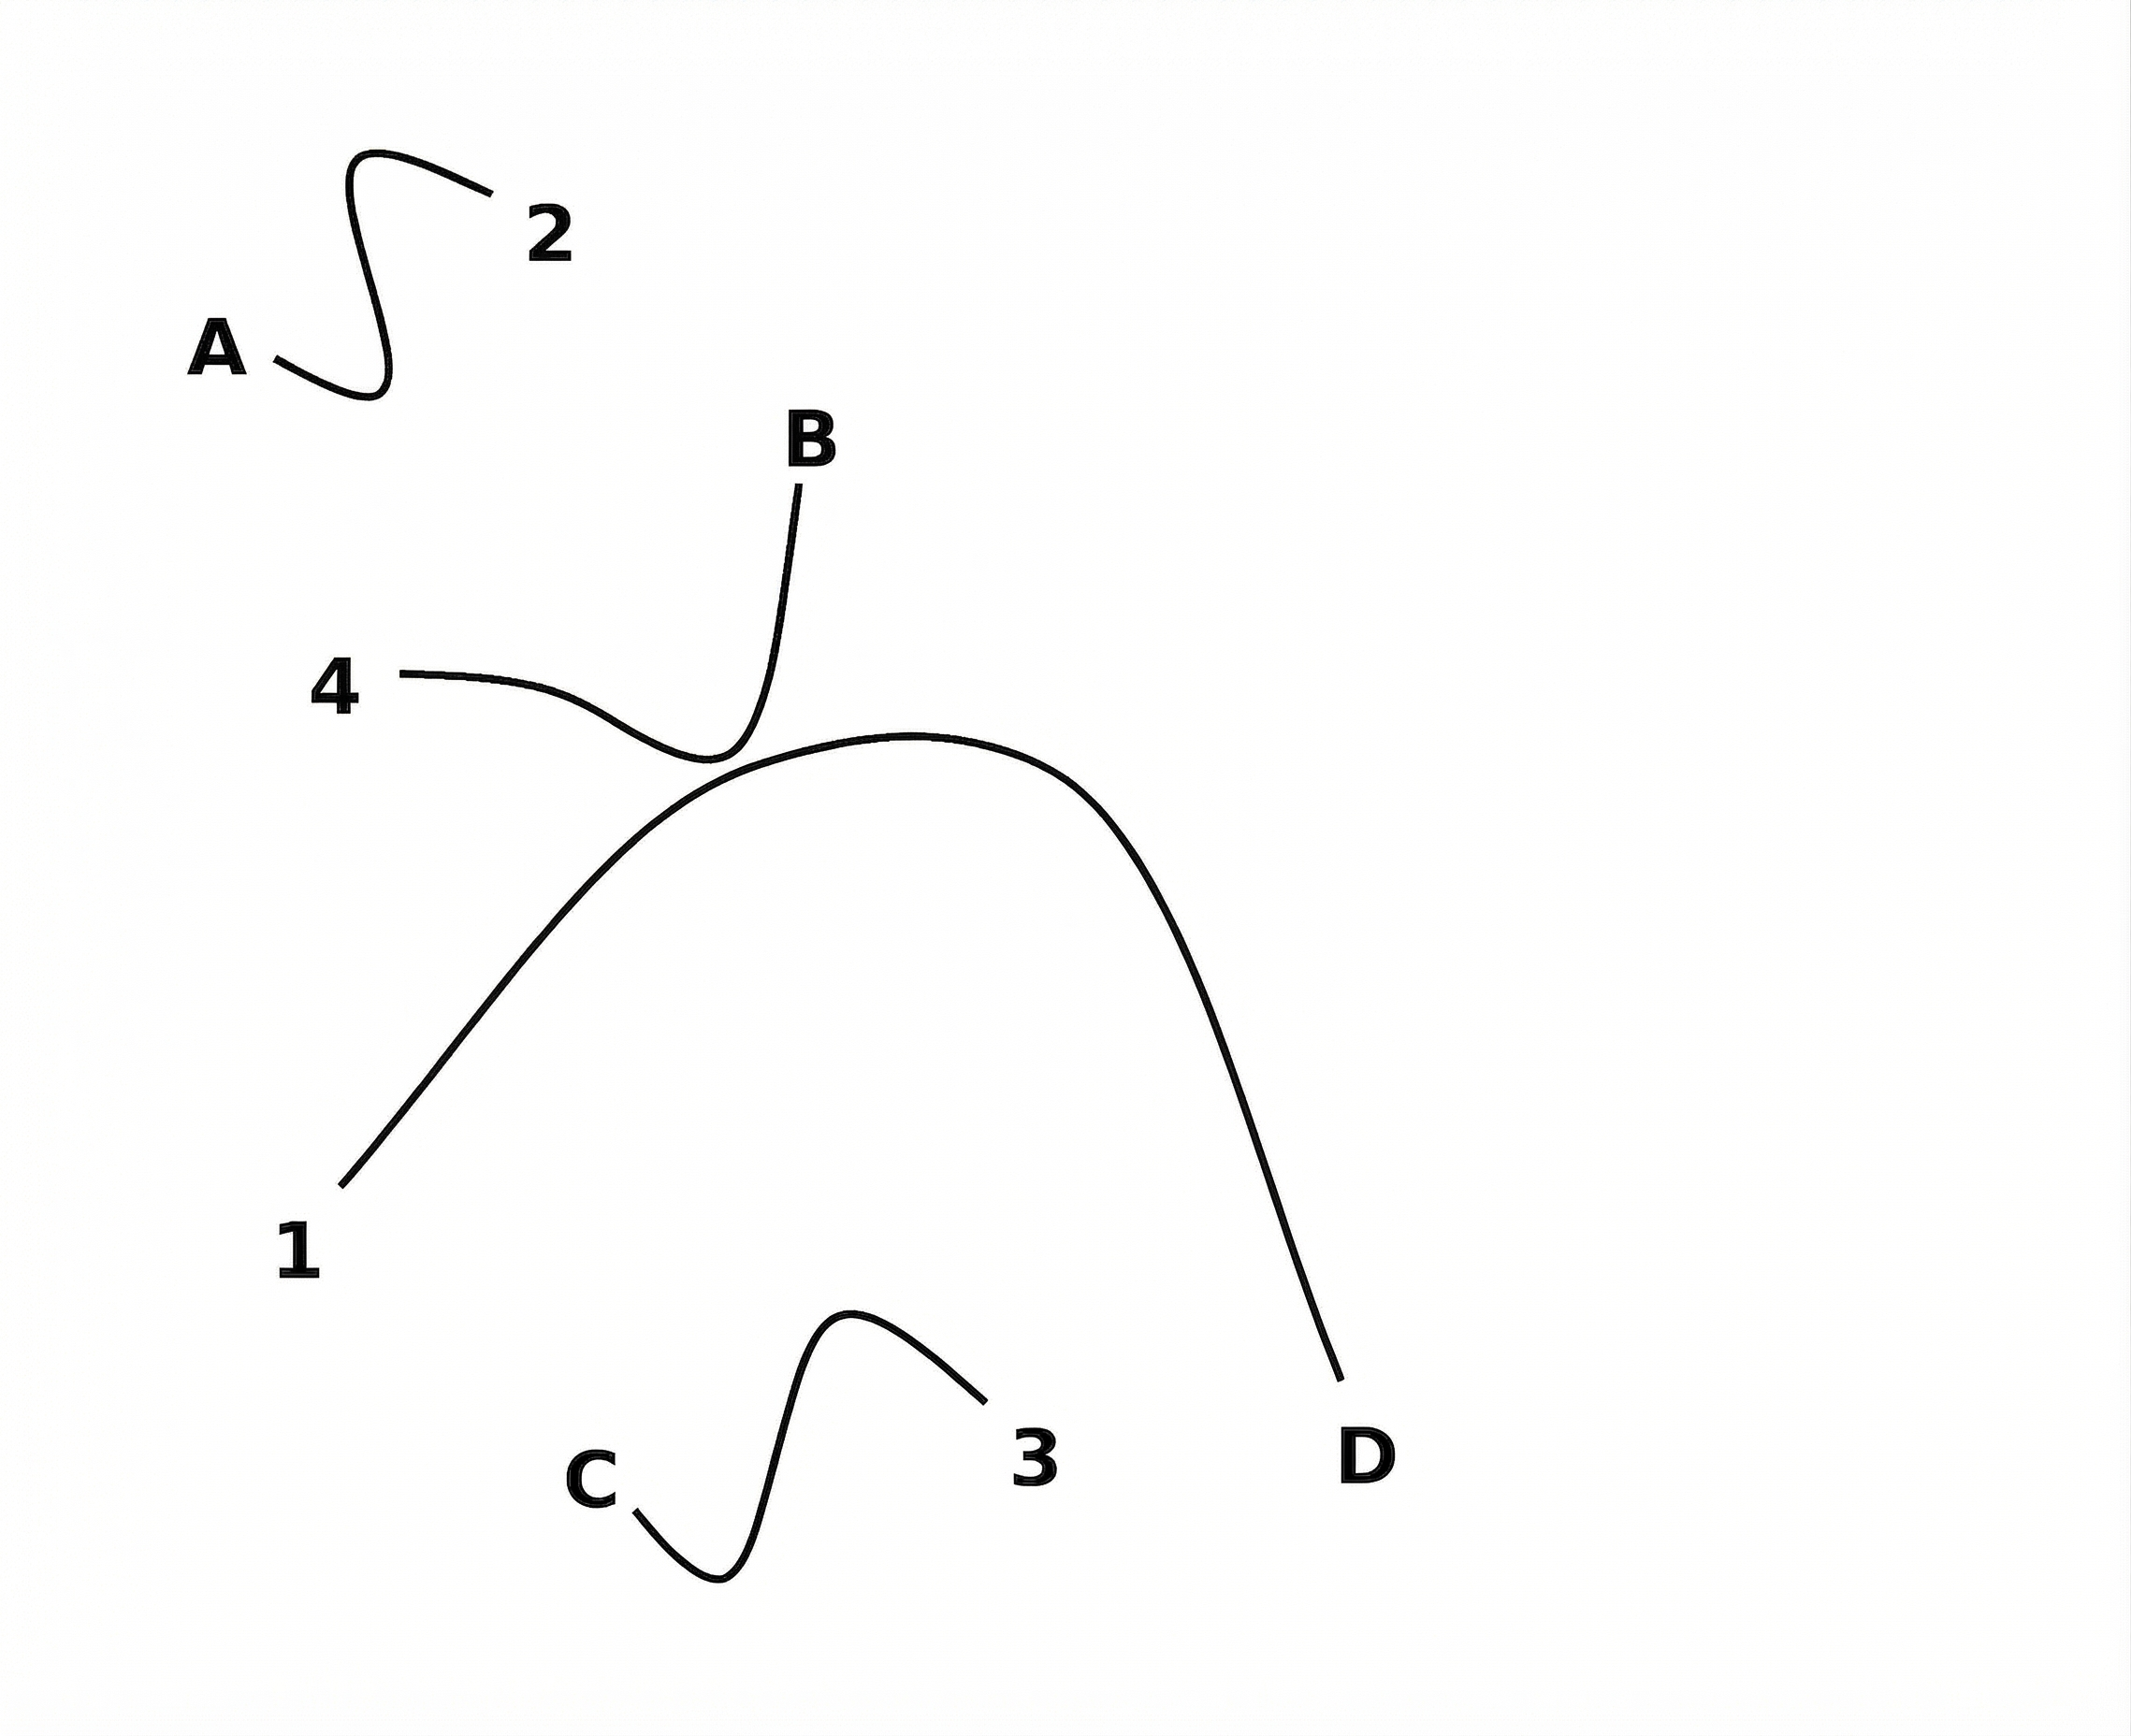
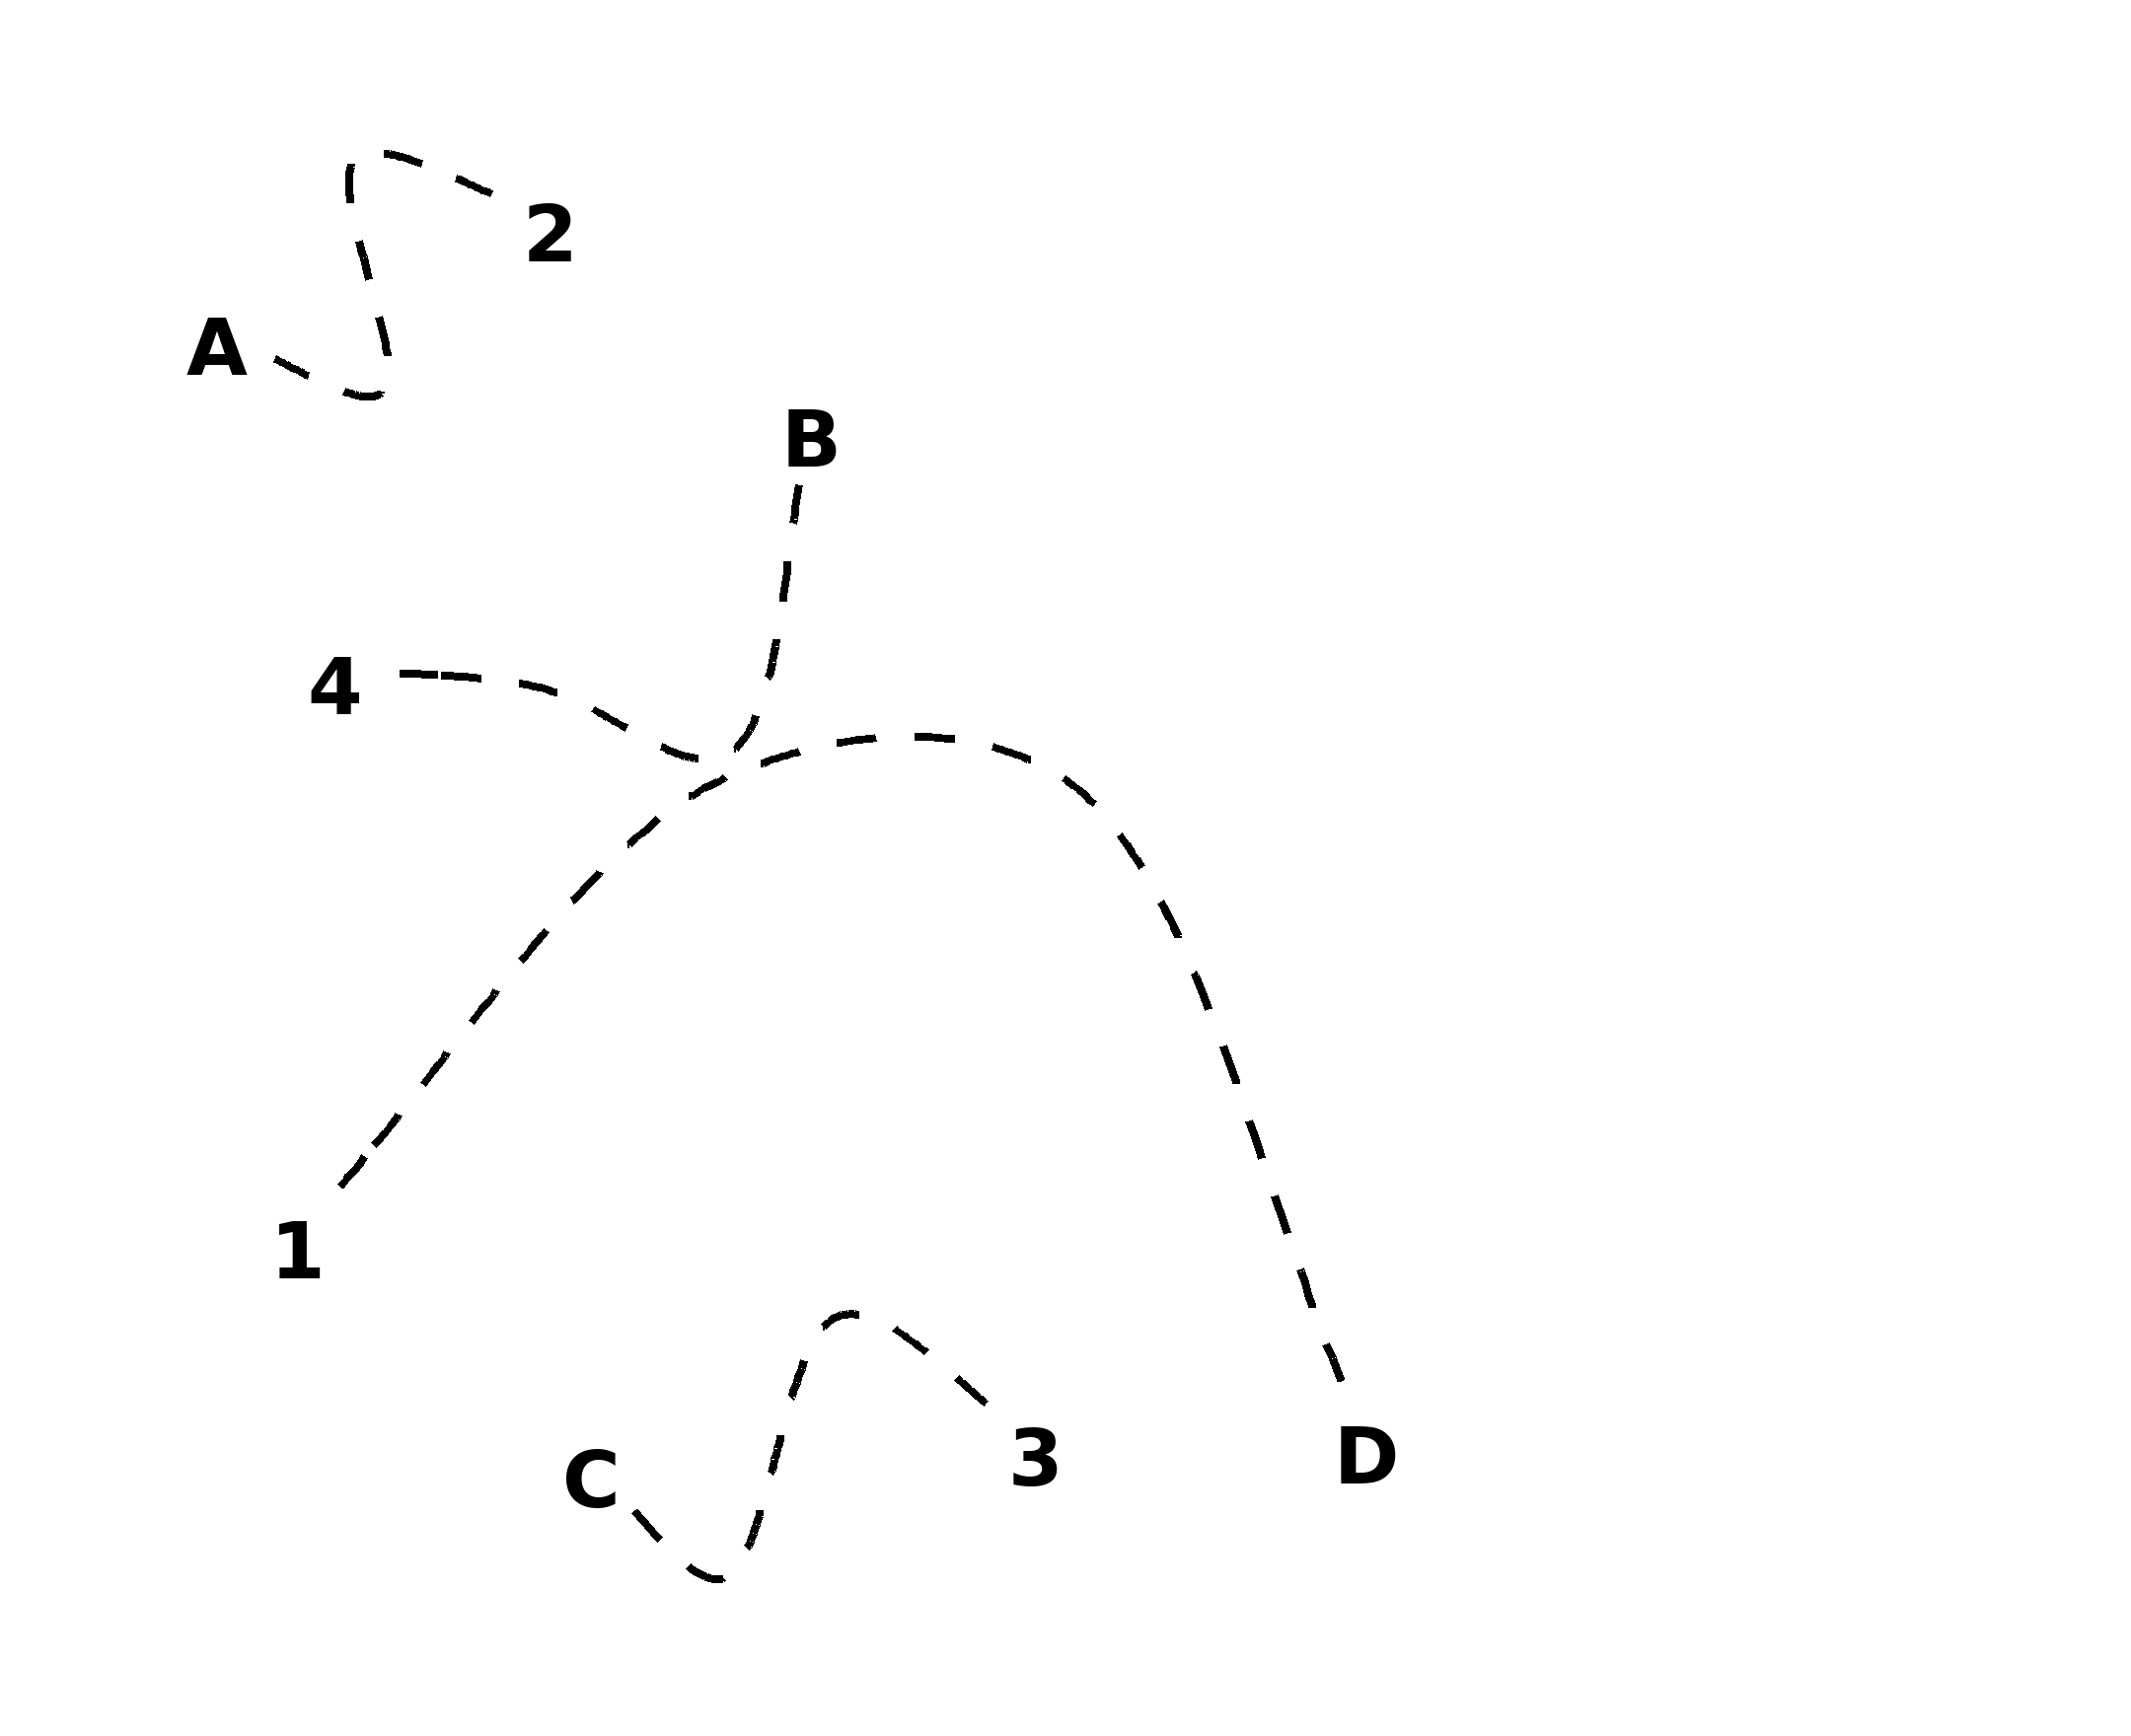
Trace the lines to match each number (1, 2, 3, 4) to its corresponding letter (A, B, C, D).

Dashed paths connecting numbers 1 to 4 and letters A to D
Text-only

Answer: BACD ✕

ReImaGin

I can use the generate_image tool to convert the dashed lines into solid lines, which will make it easier to trace the paths without ambiguities.

generate_image(“convert the dashed lines into solid lines. do not change the layout or anything else.”)
Generated solid paths connecting the numbers and letters

Answer: DACB ✓

Strategy discovery

The model can discover how to use image generation.

Different problems need different generated images: colored lines for the tracing task above, or a panorama to connect room views below. Instead of choosing these strategies by hand, ReImaGin proposes natural-language image instructions, tests them on a small development set, and keeps the most useful ones.

User

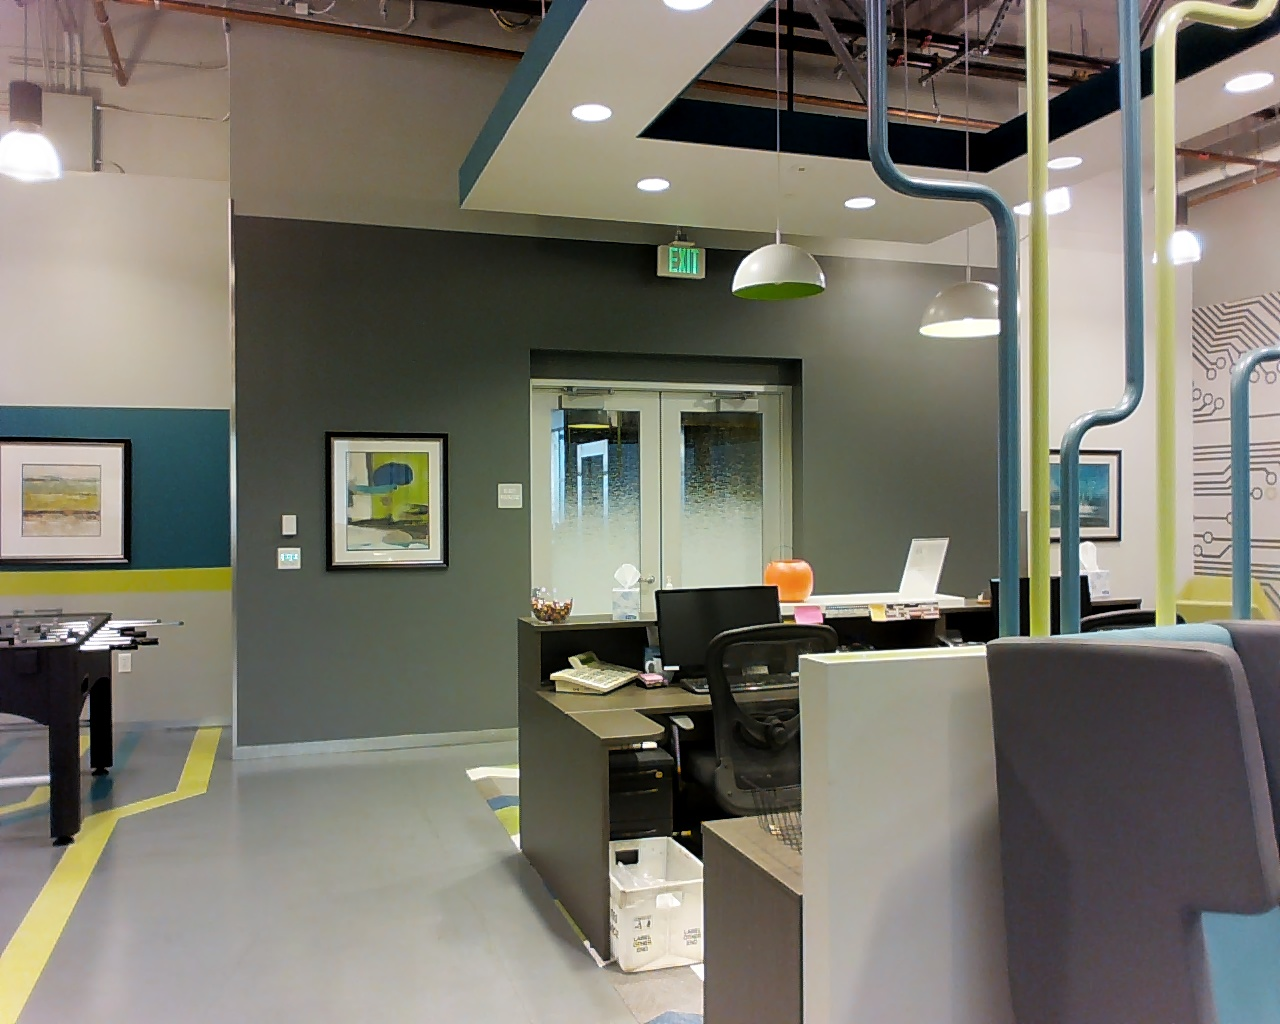
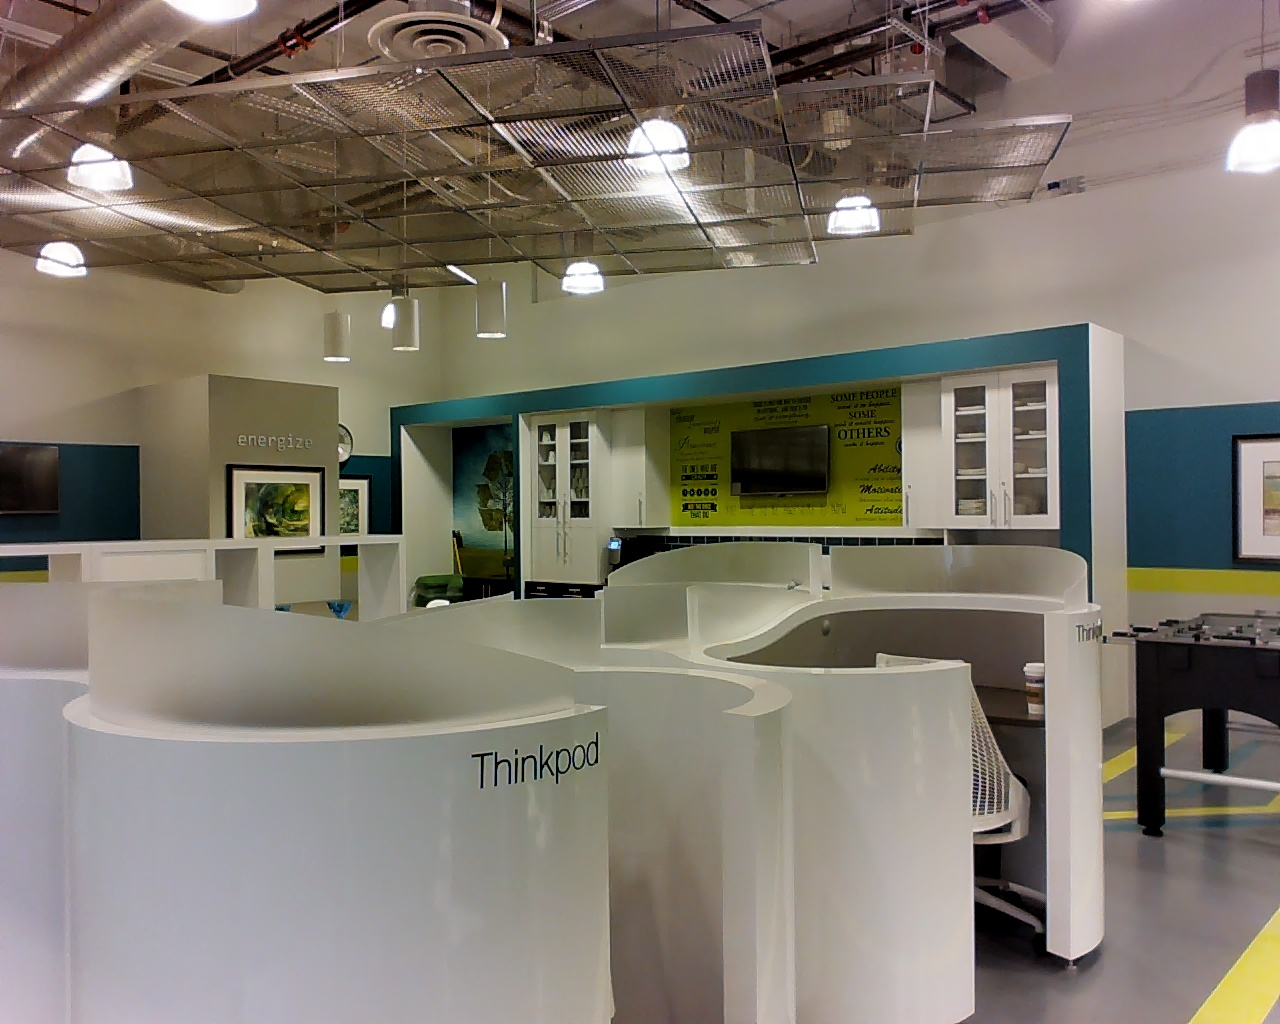
When you enter the room through the white door, which way should you go to reach the TV area?

A: Go straight · B: Go left · C: Cannot be determined · D: Go right

First view of the room Second overlapping view of the room
ReImaGin

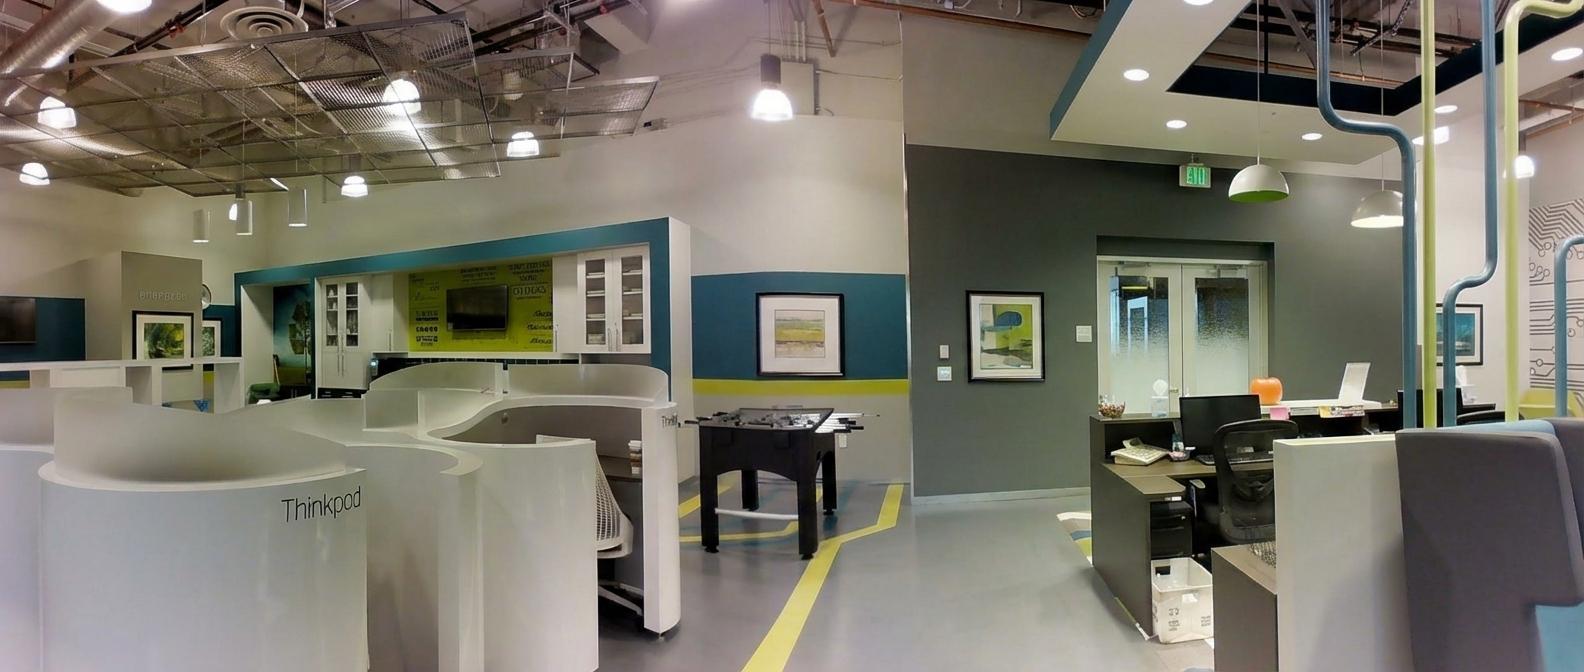
The scene is split across two images, making relative positioning hard to track. I will use generate_image to seamlessly stitch these two images together into a single ultra-wide panoramic image based on their shared visual features (the foosball table and the framed picture on the teal wall).

generate_image(“Stitch these two overlapping images into a single continuous wide-angle panorama, seamlessly blending the shared overlap area (the foosball table and the framed picture on the teal wall) so the entire room is visible in one shot.”)
Generated panorama joining the two room views

In the generated panorama, the white double doors are on the right side, and the TV area (on the green wall) is on the left side. If you enter the room through the white doors, you would be facing the camera's position. From that perspective, the left side of the image corresponds to your right. Therefore, to reach the TV area, you should go right.

Answer: D — Go right ✓

Beats text-only reasoning and specialized vision tools.

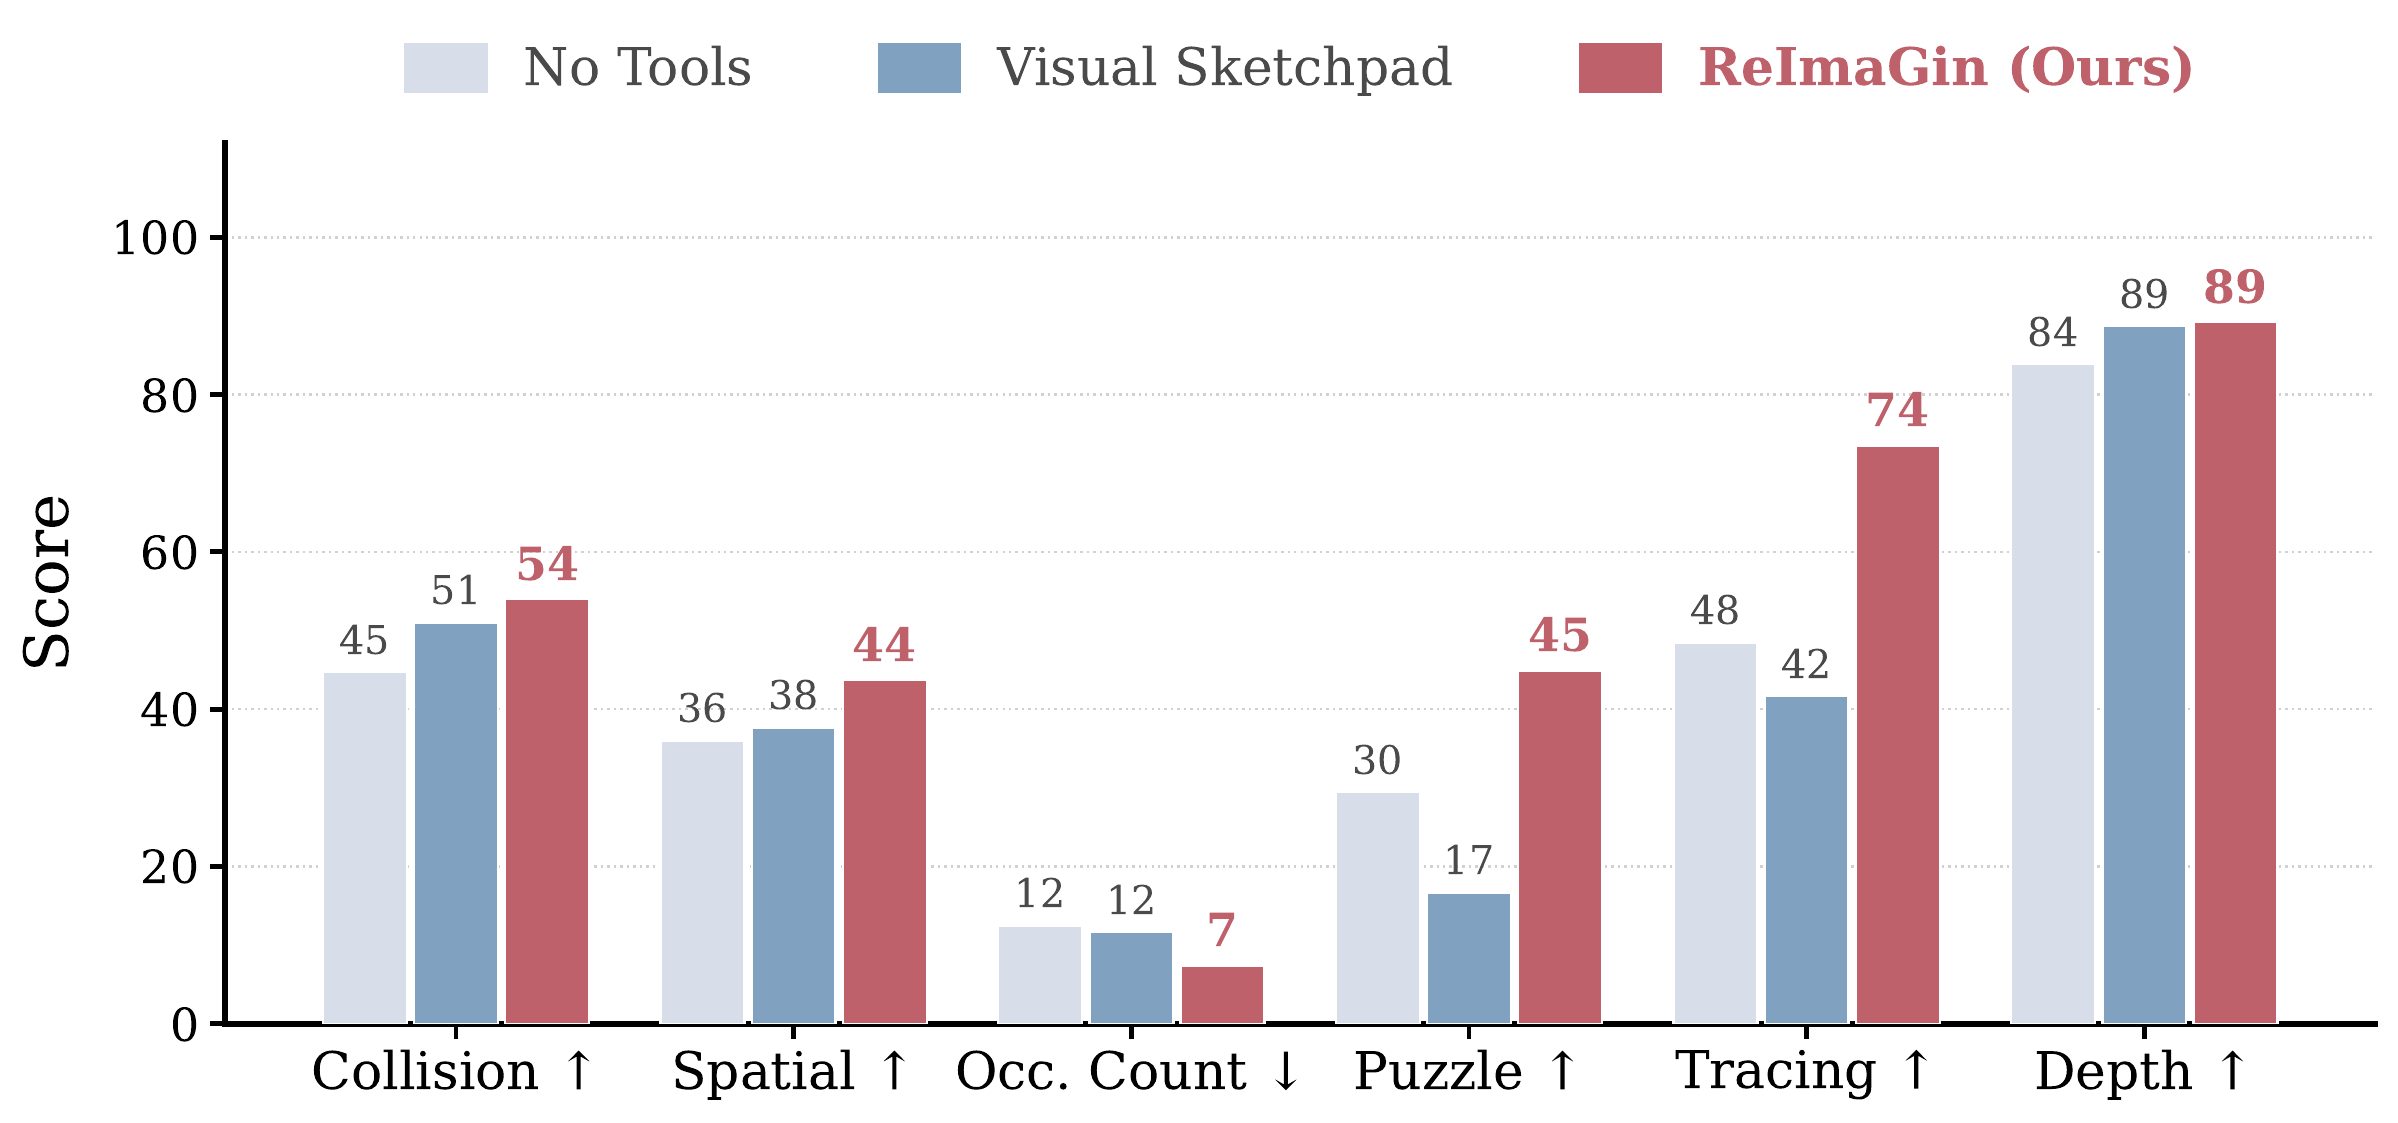
One image-generation tool improves performance across spatial reasoning, occlusion, visual puzzles, collision prediction, path tracing, and depth.

GPT-5 results comparing No Tools, Visual Sketchpad, and ReImaGin across six tasks
GPT-5 results. Occlusion counting reports error, where lower is better.

Reasoning with Image Generation

Image generation as a visual reasoning mechanism.

ReImaGin lets a multimodal model request open-ended visual operations in natural language: consolidate disjoint views into a floorplan, remove an occluder, complete a pattern, or visualize a trajectory.

Nishad Singhi*†, Hector Garcia Rodriguez*†, Aditya Arora†, Marcus Rohrbach, Anna Rohrbach

* Equal contribution · † Core contributor · TU Darmstadt & hessian.AI · COLM 2026

BibTeX

@inproceedings{singhi2026reasoning,
  title     = {Reasoning with Image Generation},
  author    = {Singhi, Nishad and Garcia Rodriguez, Hector and
               Arora, Aditya and Rohrbach, Marcus and Rohrbach, Anna},
  booktitle = {Third Conference on Language Modeling},
  year      = {2026},
  url       = {https://openreview.net/forum?id=jWMw2roMnh}
}